CoFL-S: Spatially Queryable Sector Flow Fields for Local Language-Conditioned Navigation
Jul 1, 2026· ,,,,,,,·
1 min read
Haokun Liu
Zhaoqi Ma
Yicheng Chen
Wentao Zhang
Masaki Kitagawa
Zicen Xiong
Jinjie Li
Moju Zhao
Abstract
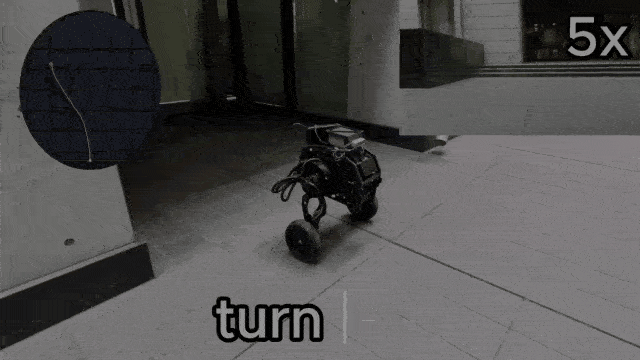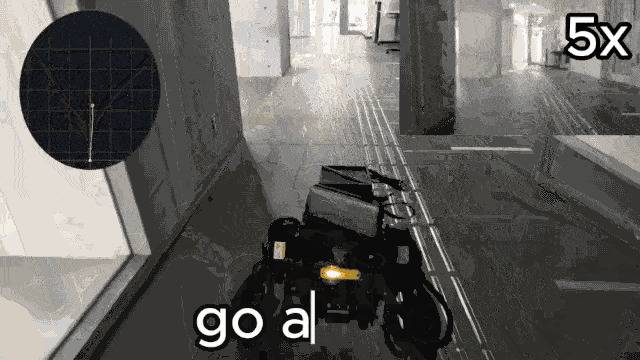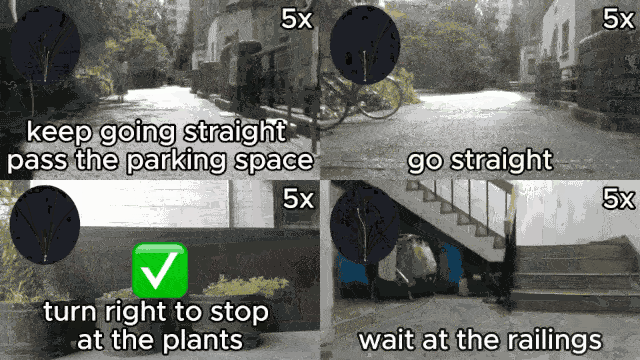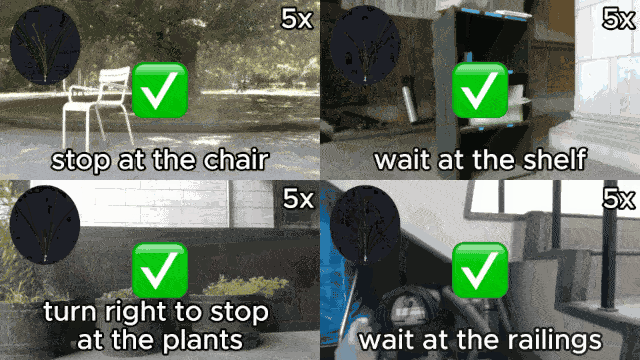
CoFL-S is a low-level vision-language-action framework that predicts a language-conditioned flow field over the robot’s local visible sector and generates continuous trajectories by rolling out the predicted field. To train this low-level representation, each VLN-CE episode — originally a whole-episode instruction paired with an action sequence — is converted into frame-level local supervision with aligned sub-instructions and matched action, trajectory, and dense flow-field targets.
Type
Publication
Conference on Robot Learning (CoRL 2026)
Video

Authors
PhD Student
I am a PhD student at the DRAGON Lab,
The University of Tokyo, advised by Junior Assoc. Prof.
Moju Zhao.
My research focuses on vision-language-action (VLA) models and
language-conditioned navigation for aerial and ground robots.