Hierarchical Language Models for Semantic Navigation and Manipulation in an Aerial-Ground Robotic System
Jan 1, 2026· ,,,,,,·
1 min read
Haokun Liu
Zhaoqi Ma
Yunong Li
Junichiro Sugihara
Yicheng Chen
Jinjie Li
Moju Zhao
Abstract
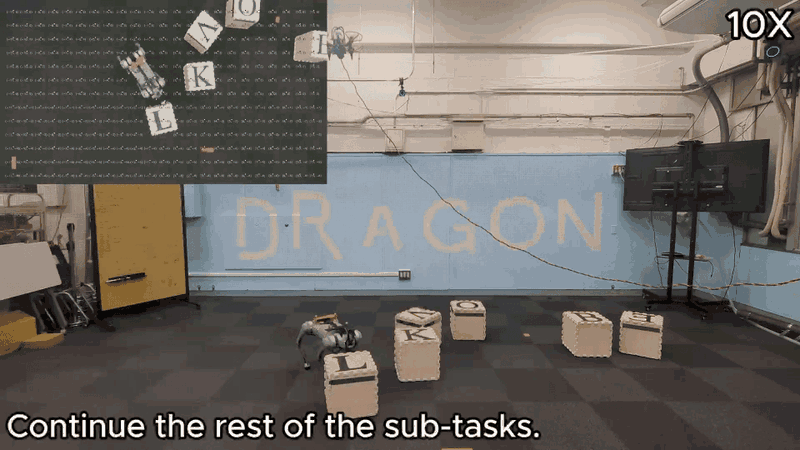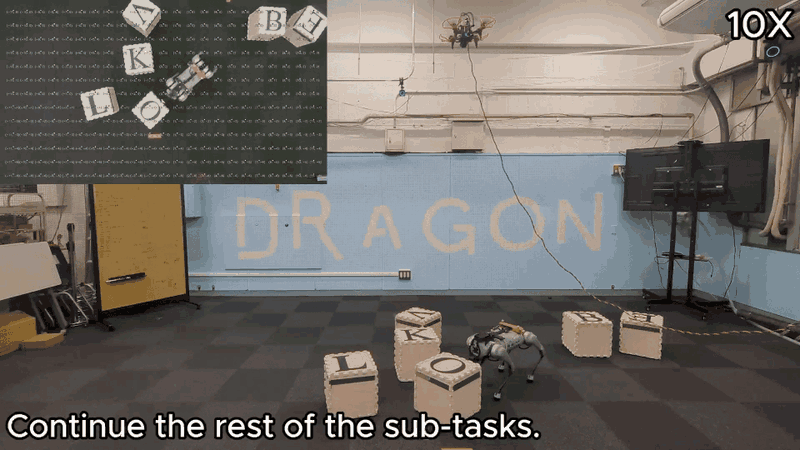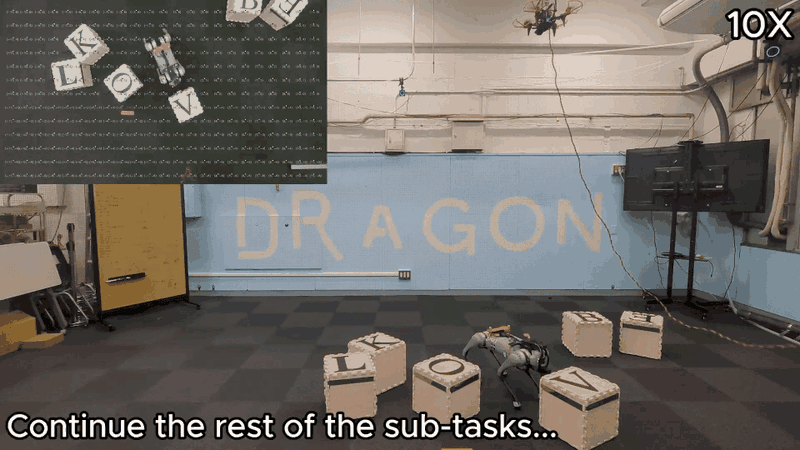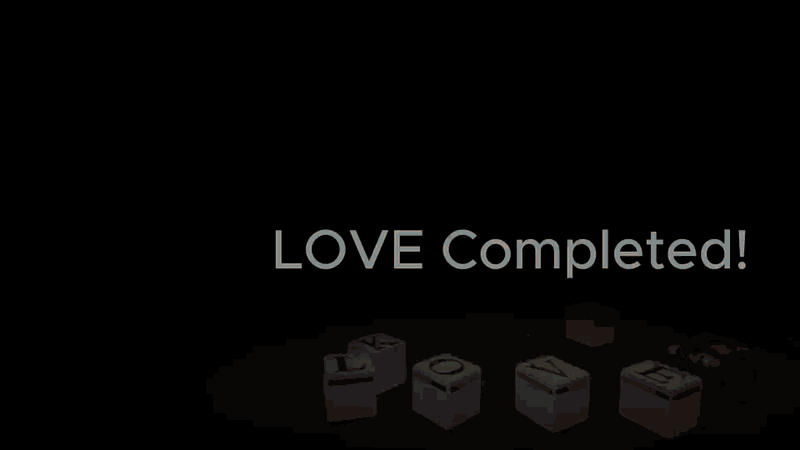
Heterogeneous multi-robot systems show great potential in complex tasks requiring coordinated hybrid cooperation, yet traditional approaches relying on static models often struggle with task diversity and dynamic environments. We propose a hierarchical framework integrating a prompted large language model (LLM) and a GridMask-enhanced fine-tuned vision language model (VLM): the LLM performs task decomposition and global semantic map construction, while the VLM extracts task-specified semantic labels and 2D spatial information from aerial images to support local planning. The aerial robot follows a globally optimized semantic path and continuously provides bird-view images that guide the ground robot’s local semantic navigation and manipulation, including target-absent scenarios where implicit alignment is maintained. To our knowledge, this is the first demonstration of an aerial-ground heterogeneous system integrating VLM-based perception with LLM-driven task reasoning and motion planning.
Type
Publication
Advanced Intelligent Systems
Video

Authors
PhD Student
I am a PhD student at the DRAGON Lab,
The University of Tokyo, advised by Junior Assoc. Prof.
Moju Zhao.
My research focuses on vision-language-action (VLA) models and
language-conditioned navigation for aerial and ground robots.